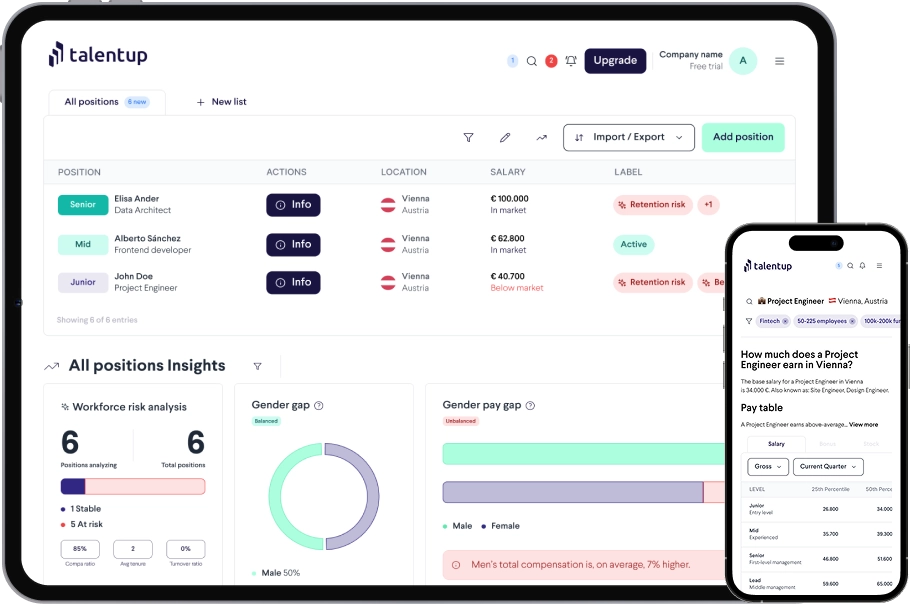
Understanding how TalentUp’s data is built helps you use it with confidence. This section explains where the salary data comes from, how it is processed, and what the Confidence Ratio means when you are reading a benchmark result.
Where Does the Data Come From?
TalentUp collects compensation data from three complementary sources, giving the platform a broad and representative view of the job market:
- 72% Job Boards
The majority of TalentUp’s data comes from hundreds of public job portals, scraped daily to capture job descriptions, salary offers, location, benefits, and company metadata. This provides a real-time pulse on what companies are actively offering in the market. - 17% Employee-Submitted Profiles on TalentUp.io
Employees voluntarily submit their compensation details through the TalentUp platform. Each submission is validated by comparing it against similar roles, companies, and locations to ensure accuracy and relevance. - 11% HR Datasets from Client Companies
TalentUp clients can upload anonymized internal compensation data via Excel templates or HRIS integrations. This data is included only if it was collected in the current year, keeping the dataset fresh and reliable.
4-Step Data Process
Every data point goes through a four-step pipeline before it is used in a benchmark: Collection, Normalization, Deduplication, and Validation.
1. Collection
TalentUp collects over 20,000 new salary data points per day from 300+ sources across 70+ countries and 600+ job roles. In addition to salaries, the platform captures bonuses, job descriptions, company information, and benefits, giving each benchmark a richer context.
2. Normalization
Raw data from different geographies and sources is standardized so it can be compared meaningfully. This step covers three areas:
- Currency Conversion: salaries from international sources are converted using daily exchange rates
- Job Title Translation: TalentUp’s taxonomy maps over 32,000 roles across multiple languages so that the same position is interpreted consistently regardless of how it was titled in the source
- Benefit Standardization: common benefits such as health insurance, remote work, and stock options are normalized even when described differently across sources
This makes it possible to compare a Software Engineer in Sao Paulo with the same role in Berlin or Toronto on a like-for-like basis.
3. Deduplication
Duplicate listings and repeated job offers are filtered out using natural language processing (NLP) algorithms that detect semantic similarities in job descriptions and employer metadata. This ensures every data point is unique and avoids inflated or skewed values in the final benchmark.
4. Validation
Both automated checks and manual reviews are applied before a benchmark is published:
- Benchmark Comparison: sudden changes in a benchmark (for example, a 20% salary increase in a city-role combination) trigger an automatic flag for further review
- Sample Size Threshold: a minimum of 30 data points per position and location is required before a benchmark is published, ensuring statistical reliability
- Manual Cross-Check: significant deviations from historical benchmarks or industry standards are reviewed manually and cross-verified with partner sources
All benchmarks are refreshed every 1 to 2 months, so the data you see reflects current market conditions.
Predictive Modeling
For roles, locations, or seniority levels where collected data is sparse, TalentUp uses predictive analytics to fill gaps and maintain continuous coverage without sacrificing reliability.
- Linear Regression Models
Salary trends are estimated based on seniority and experience using regression models tuned to reflect realistic career compensation growth. - Correlation Across Similar Markets
If direct data is unavailable for a given city, TalentUp estimates benchmarks by drawing on correlations with similar locations, industries, or company sizes, enabling reliable coverage even in less data-rich regions. - Data Completion
Predictive modeling allows TalentUp to provide complete salary ranges, from base pay to bonuses, even when only partial source data exists, ensuring a consistent experience across all roles and locations.
Confidence Ratio
Every benchmark in TalentUp includes a Confidence Ratio, a score from 0 to 1 that tells you how reliable that specific data point is. It is calculated from three factors:
- Sample size: how many data points underlie the benchmark
- Distribution quality: how consistent the reported salaries are with each other
- Data freshness: how recently the data was collected
Use this score to calibrate how much weight to put on a benchmark when making compensation decisions:
- 0.8 to 1.0: highly reliable; use with confidence for formal decisions such as salary bands or offer setting
- 0.6 to 0.8: solid and trustworthy; suitable for most benchmarking purposes
- Below 0.6: useful as a directional guide, but treat with some caution and consider supplementing with additional context
The maps below show the Confidence Ratio across regions, so you can quickly see where TalentUp’s data is strongest for the markets you operate in.
Europe Confidence Ratio:
window.addEventListener("message",function(a){if(void 0!==a.data["datawrapper-height"]){var e=document.querySelectorAll("iframe");for(var t in a.data["datawrapper-height"])for(var r,i=0;r=e[i];i++)if(r.contentWindow===a.source){var d=a.data["datawrapper-height"][t]+"px";r.style.height=d}}});